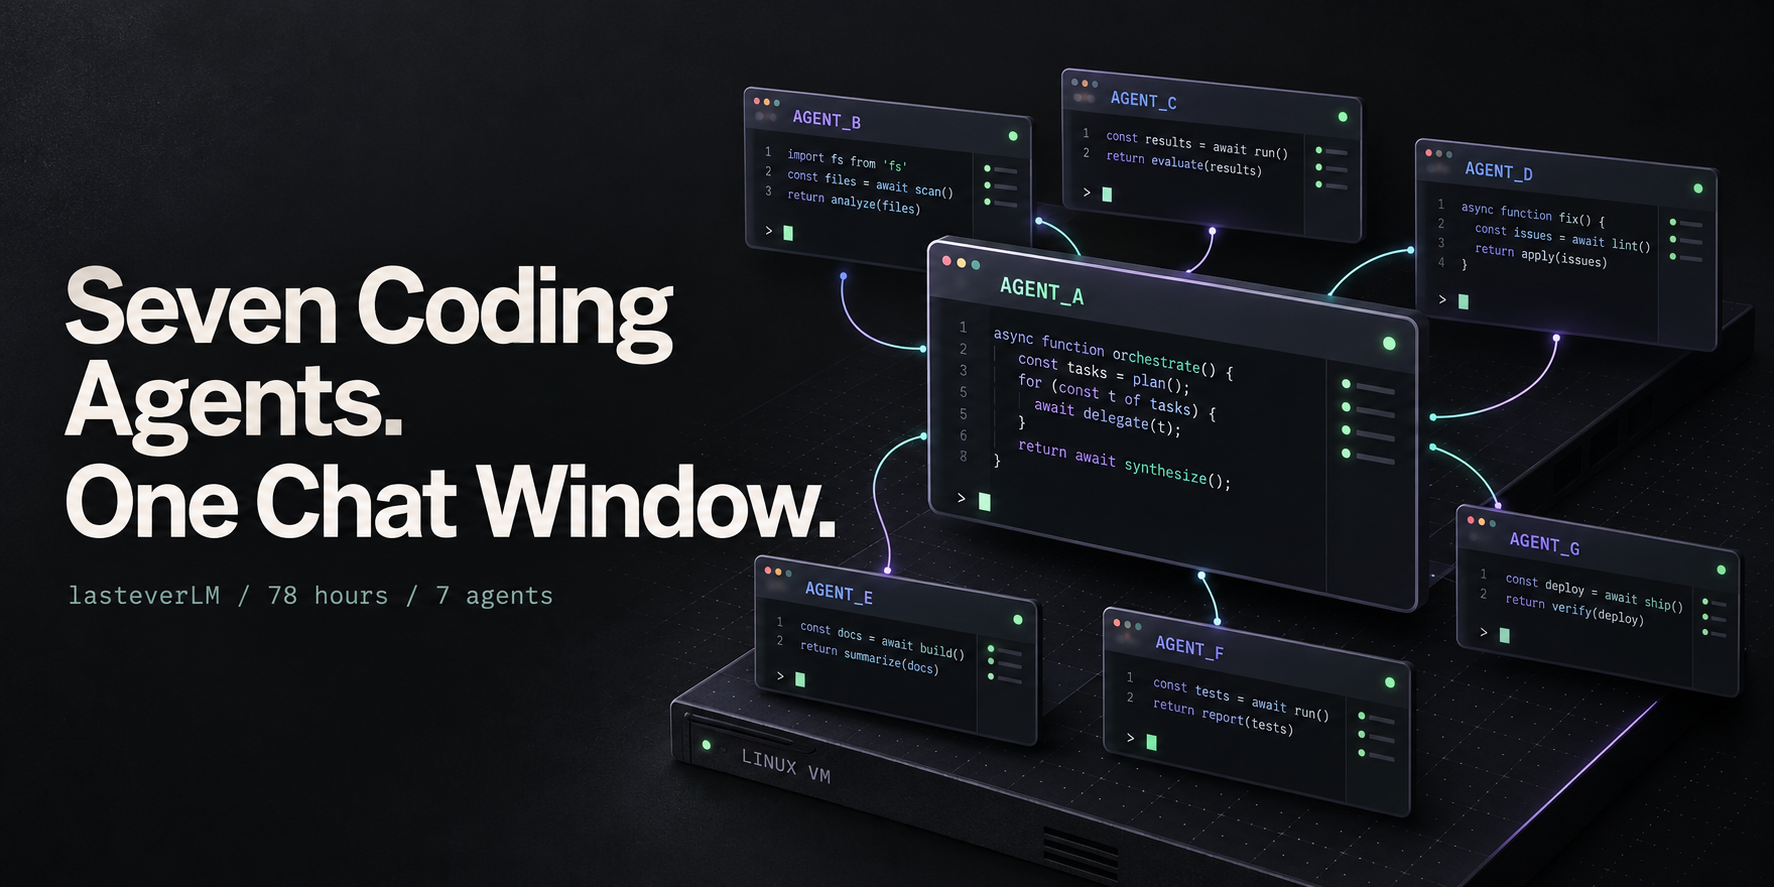
Seven Coding Agents. One Chat Window.
Building lasteverLM in 78 hours with a head agent, a Linux VM and 20–24 hours of my own time — and what I want from fleet tooling next.
Oct 18, 20267 min read50
Search for a command to run...
Building lasteverLM in 78 hours with a head agent, a Linux VM and 20–24 hours of my own time — and what I want from fleet tooling next.
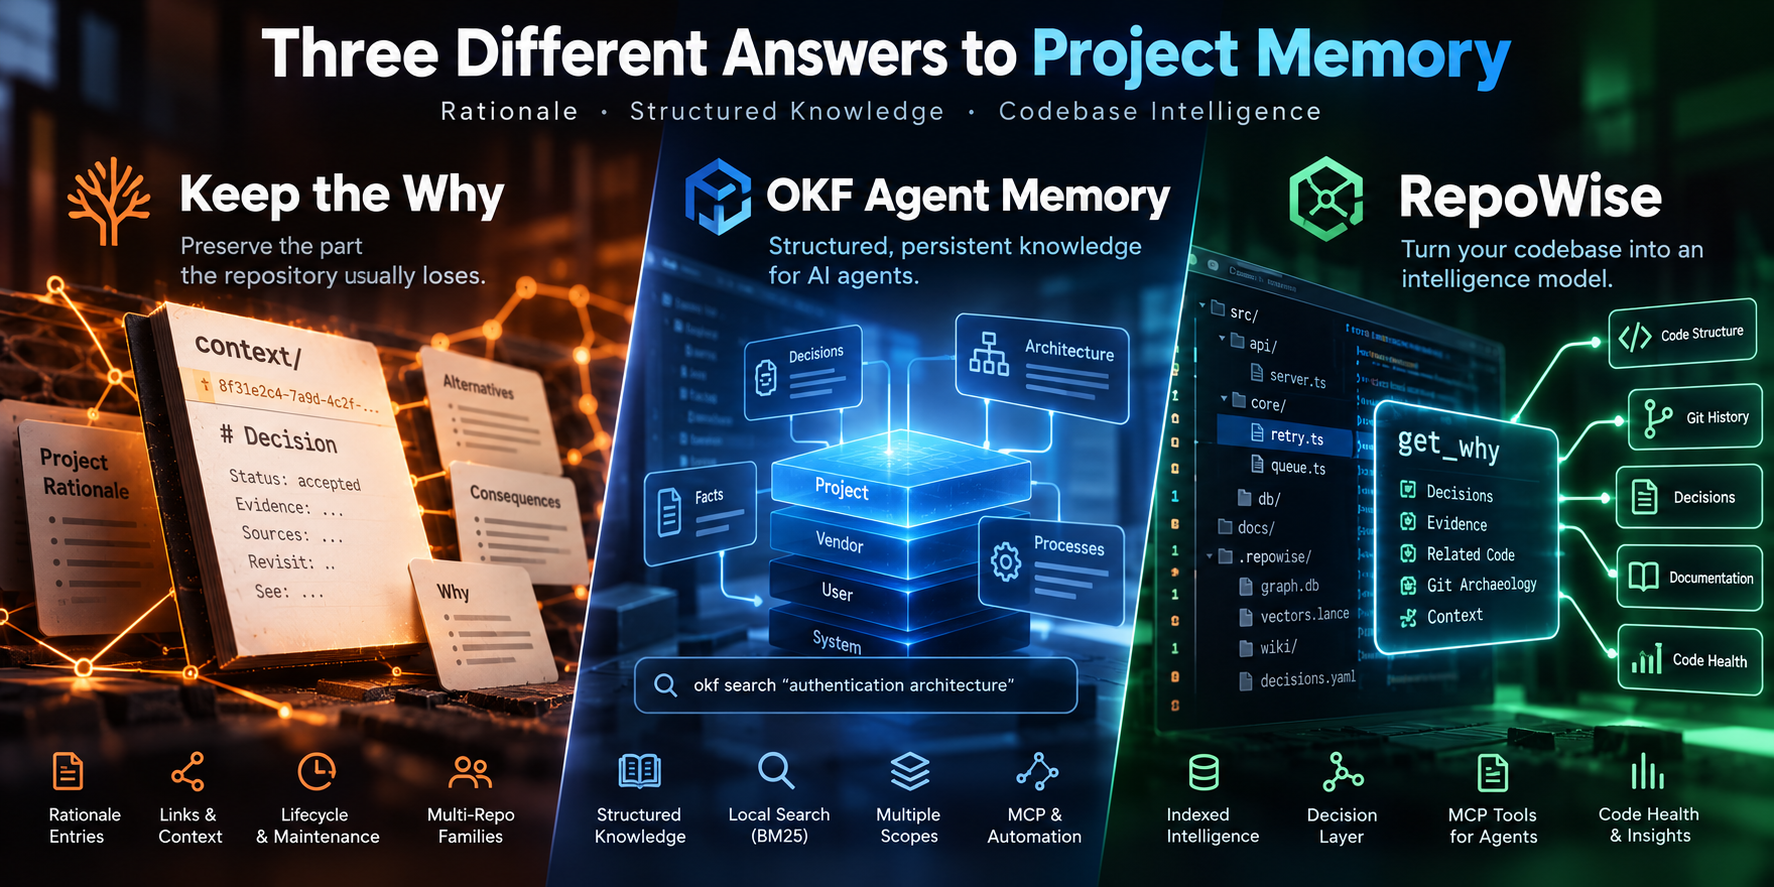
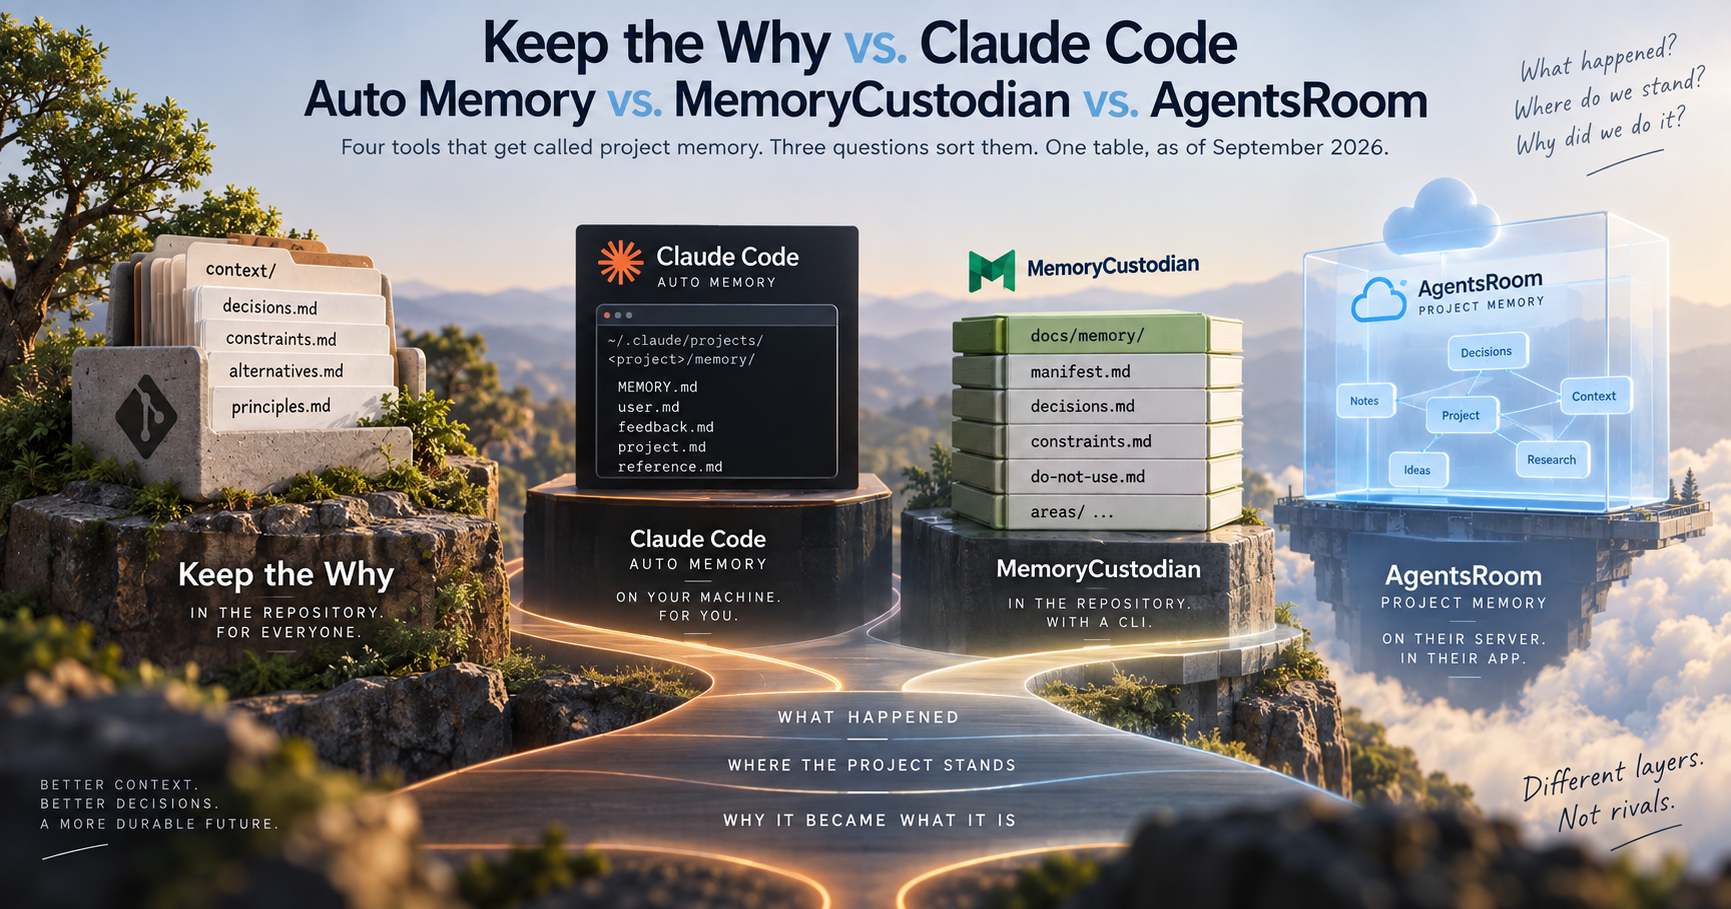
Four tools called agent memory. Four different approaches to what should survive. One puts decision rationale next to the code.
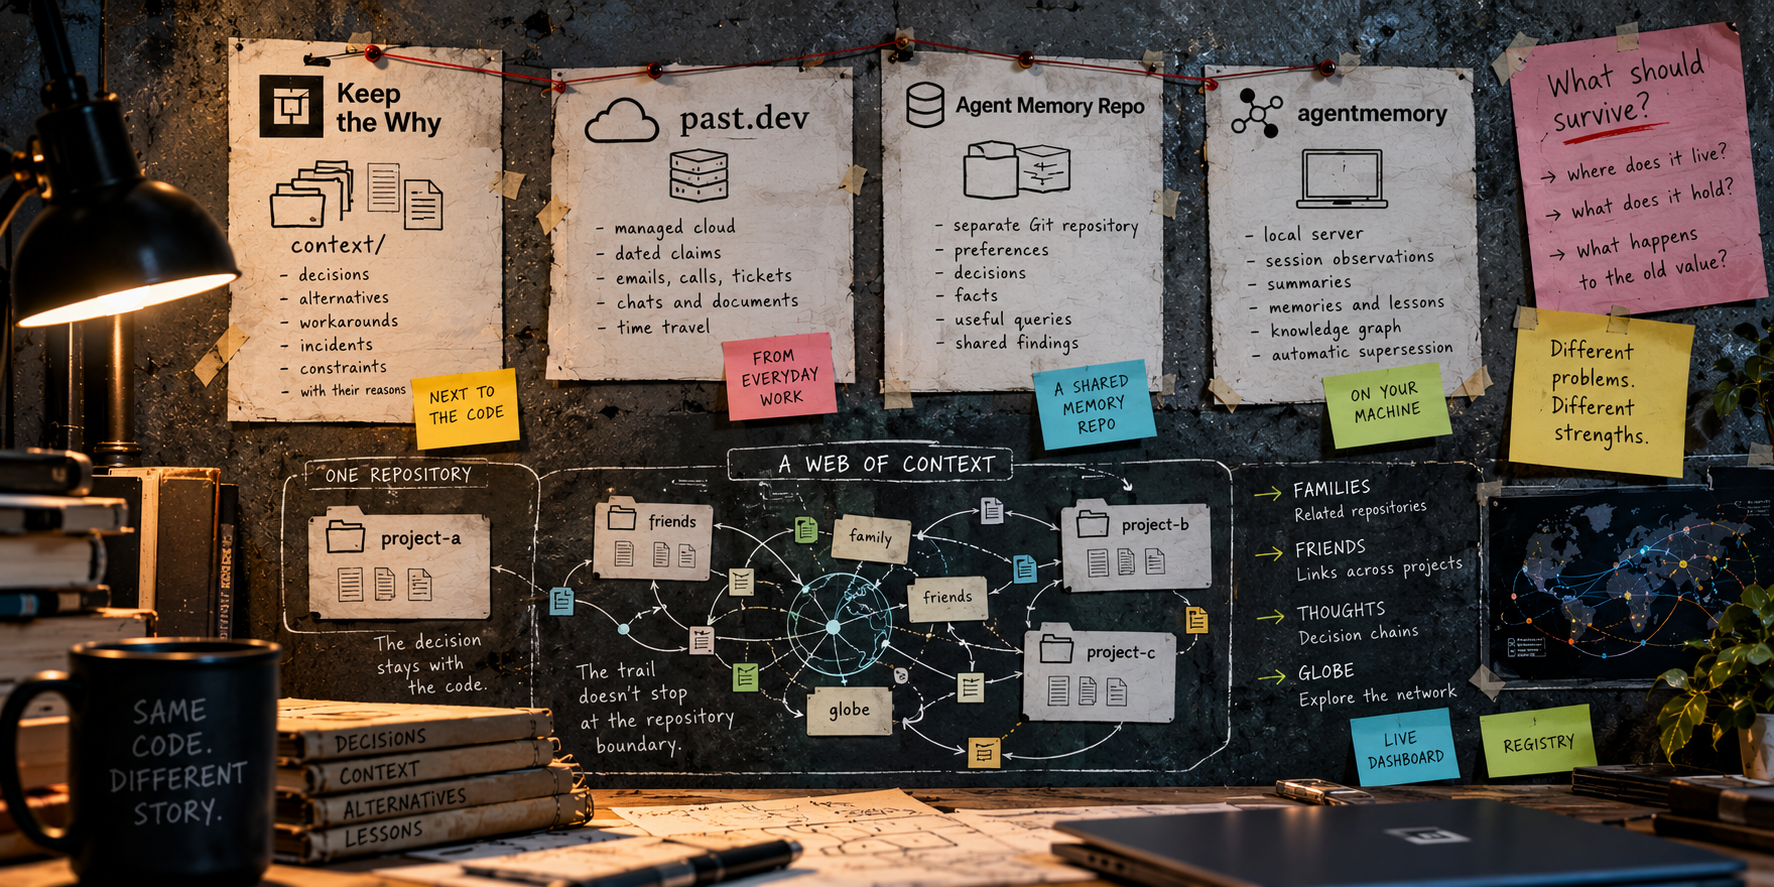
What agent evals taught me about moving model floors, noisy LLM judges, and treating the evaluator as part of the instrument
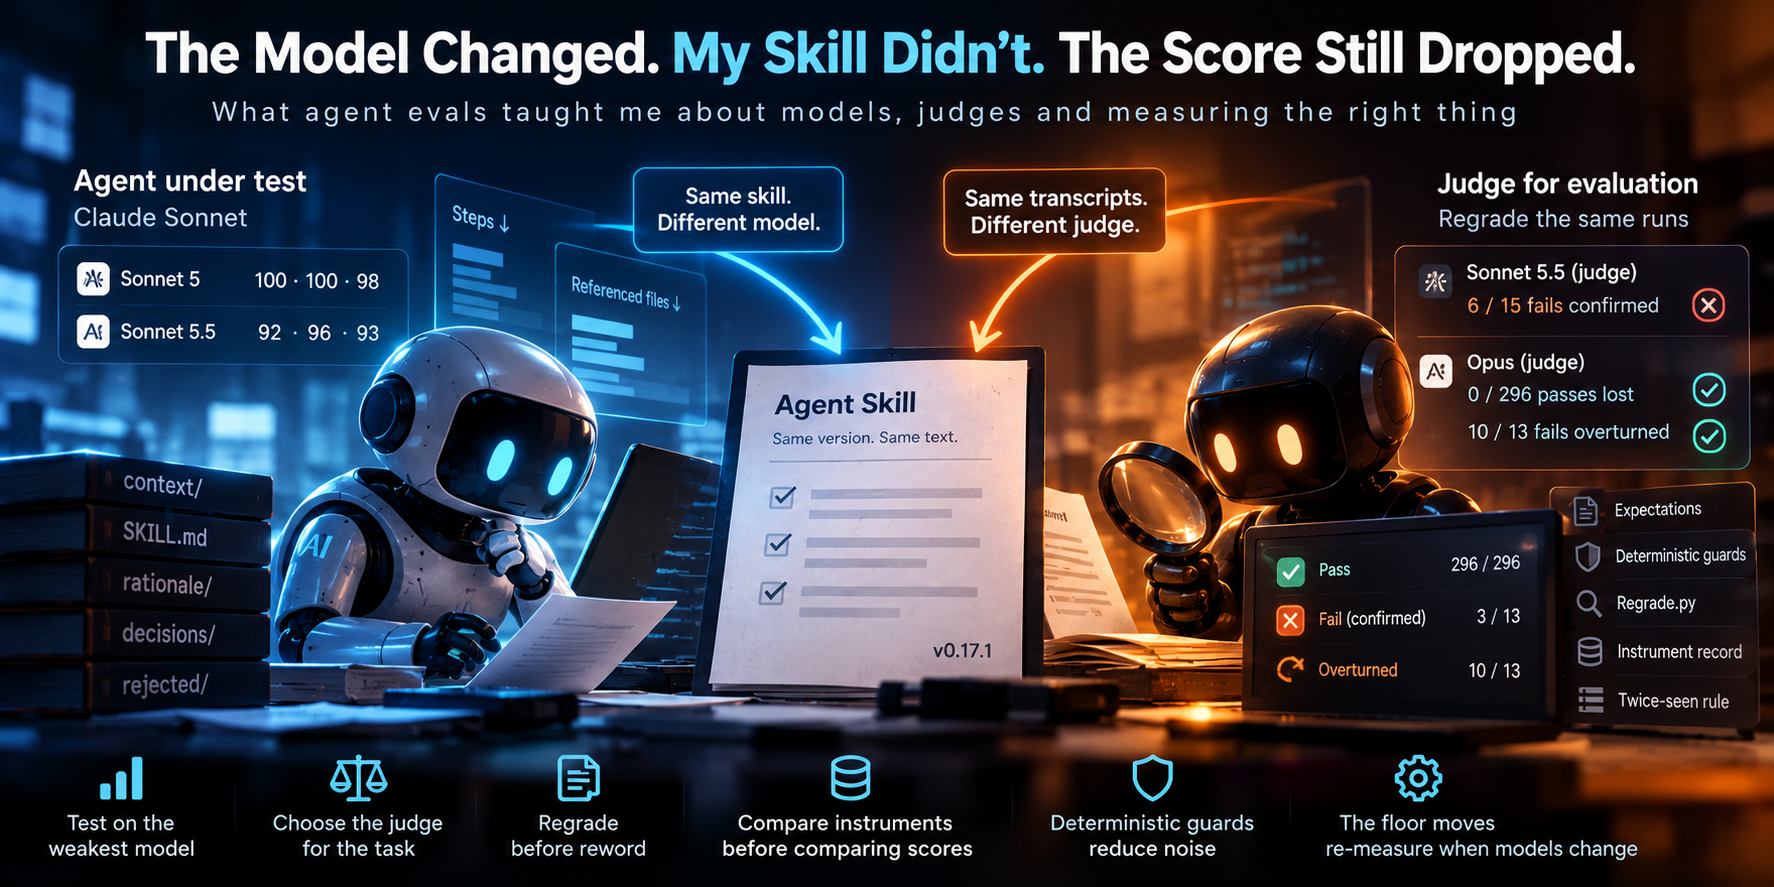
Rationale, structured knowledge, or codebase intelligence for coding agents?
Keep the Why records why a codebase is the way it is. Decisions can cite decisions in other repositories. The Globe follows those citations outward, one wave at a time, without turning project memory into a centralized service.
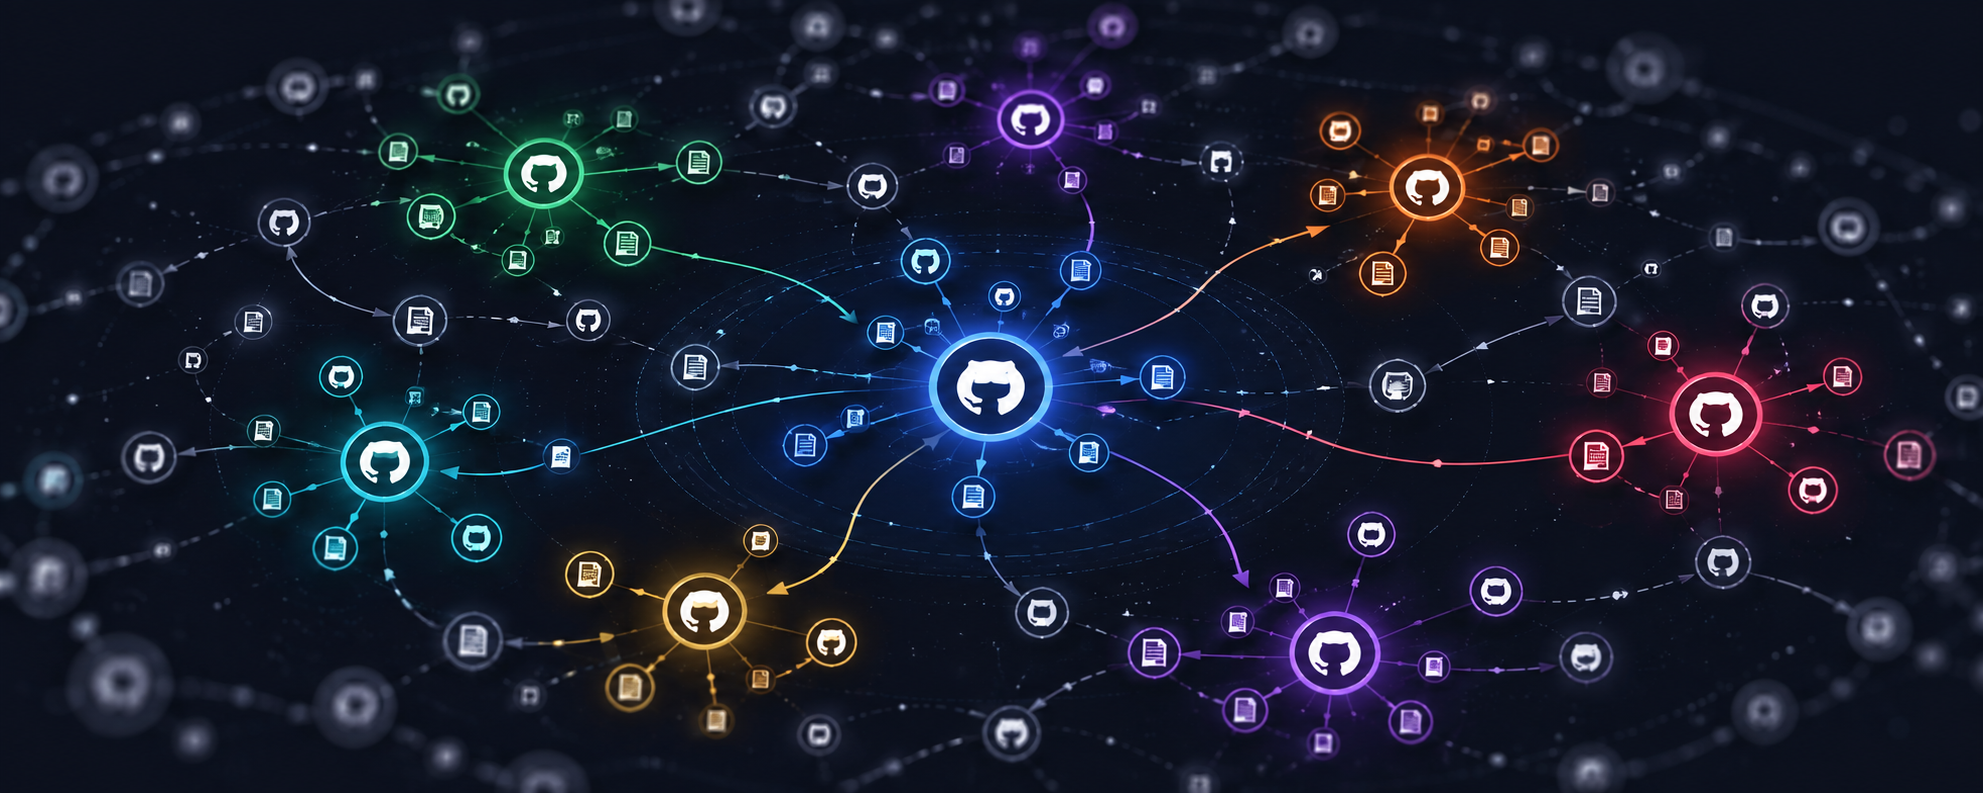
Decisions that cite each other across repositories — no graph database, no central index, no account. Just Markdown and Git.
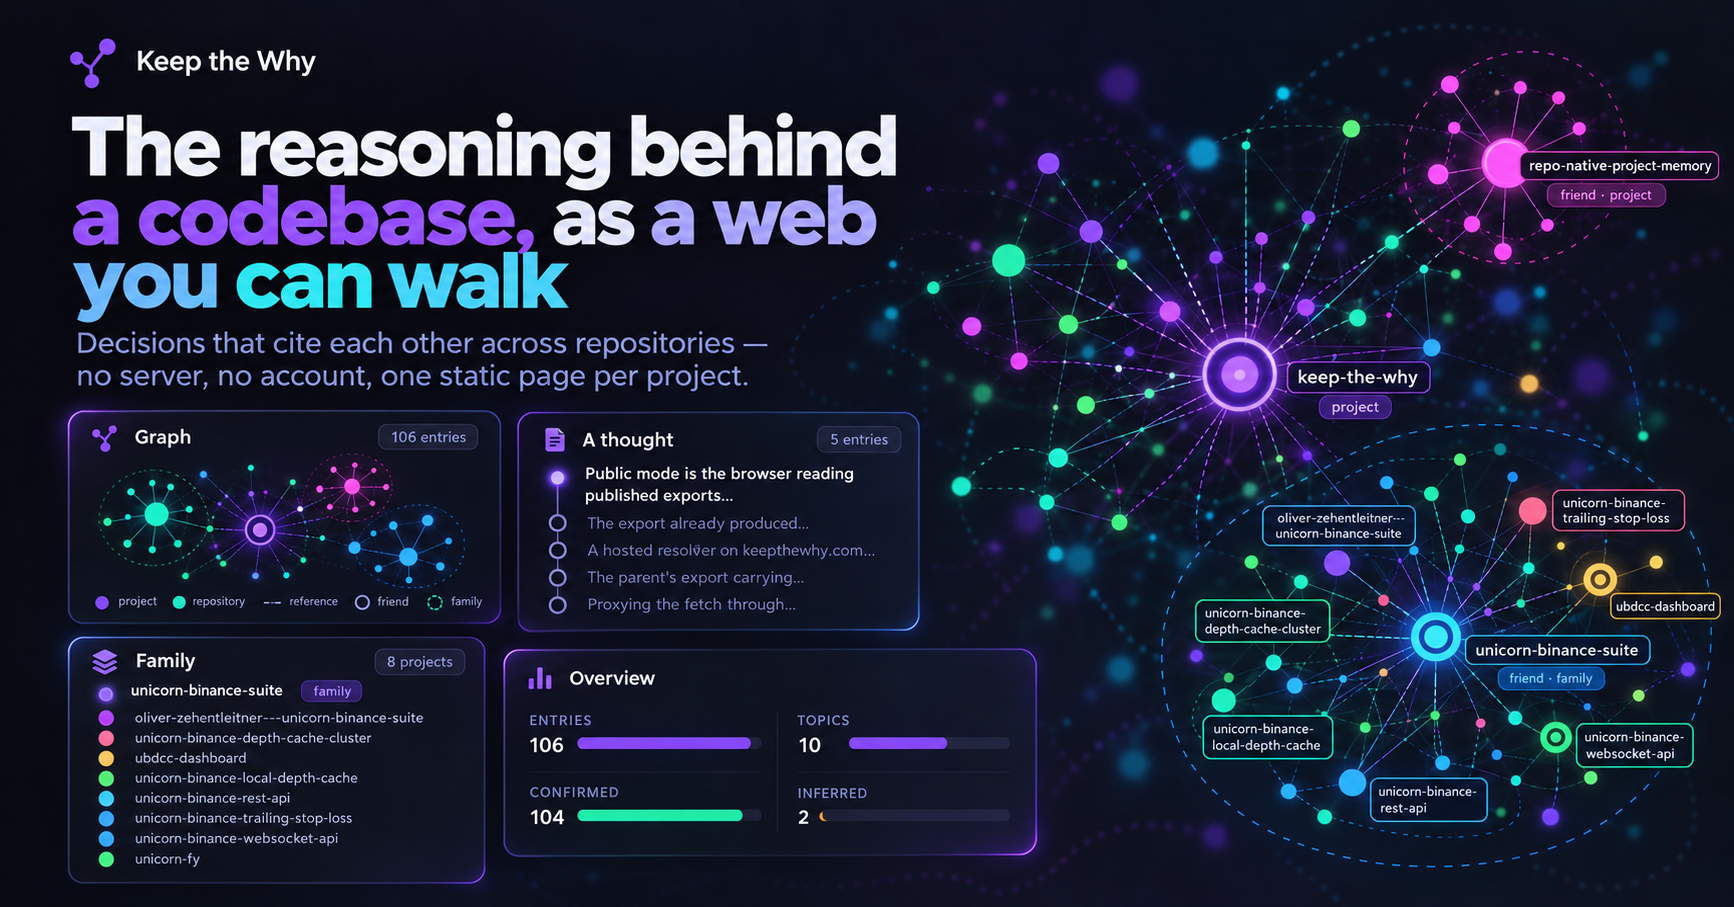
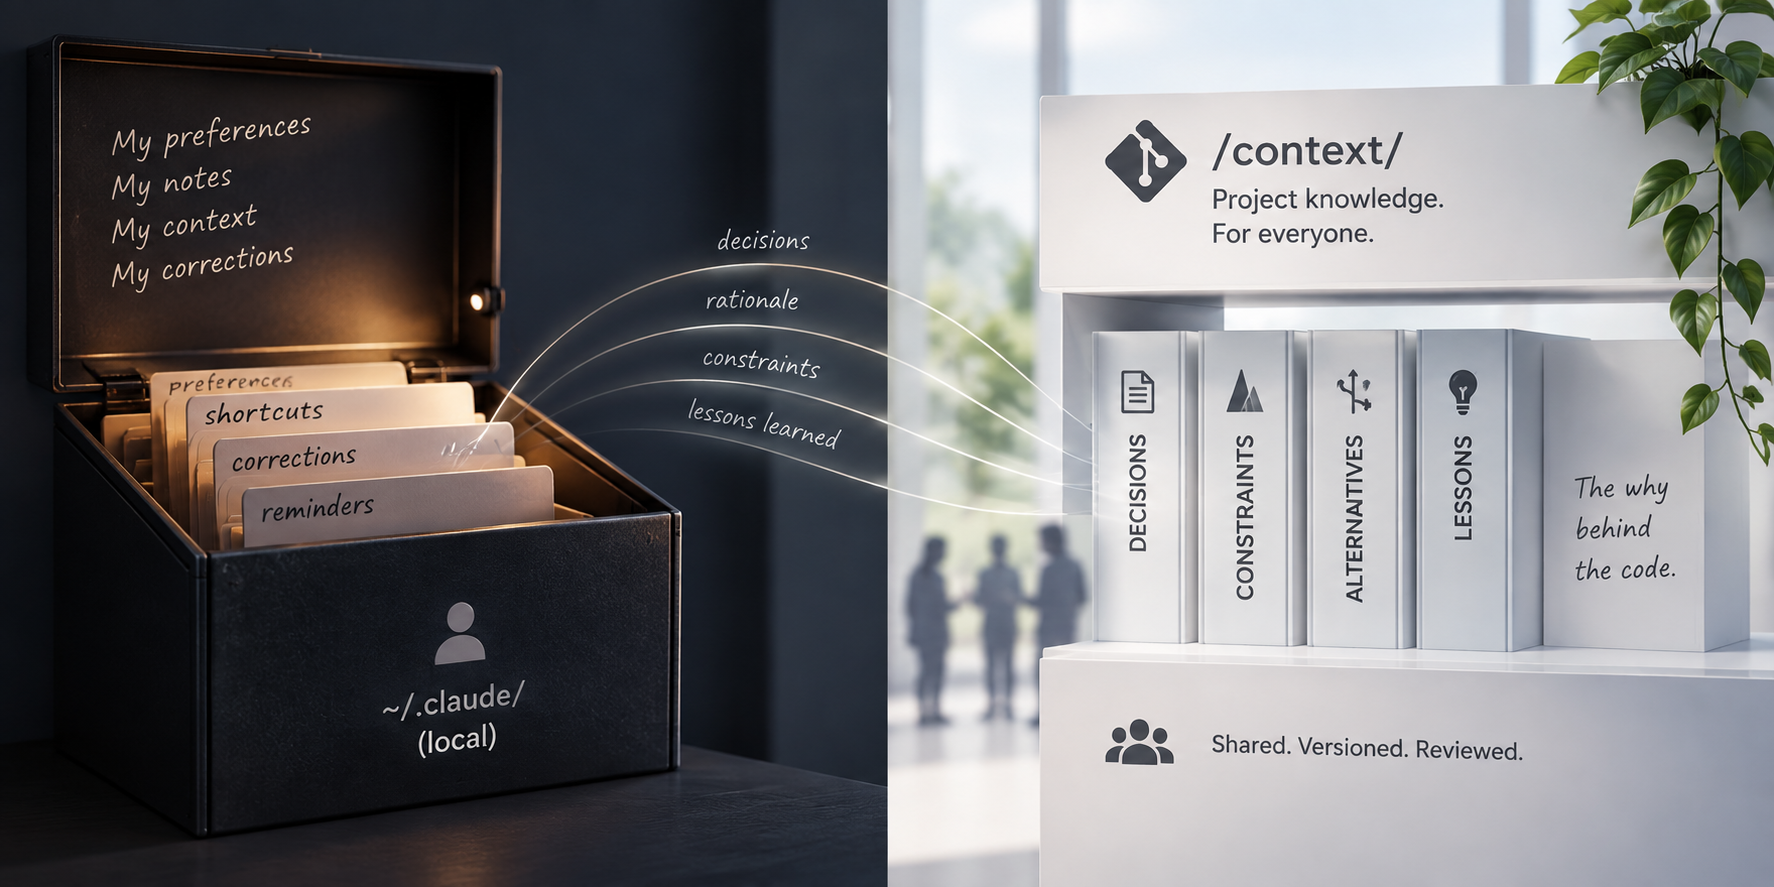
"My coding agent forgets everything between sessions." Two different things answer that, and they are not competing.
Four tools that get called project memory. Three questions sort them. One table, as of September 2026.
Install it, initialize the project, keep coding.