The Model Changed. My Skill Didn't. The Score Still Dropped.
What agent evals taught me about moving model floors, noisy LLM judges, and treating the evaluator as part of the instrument
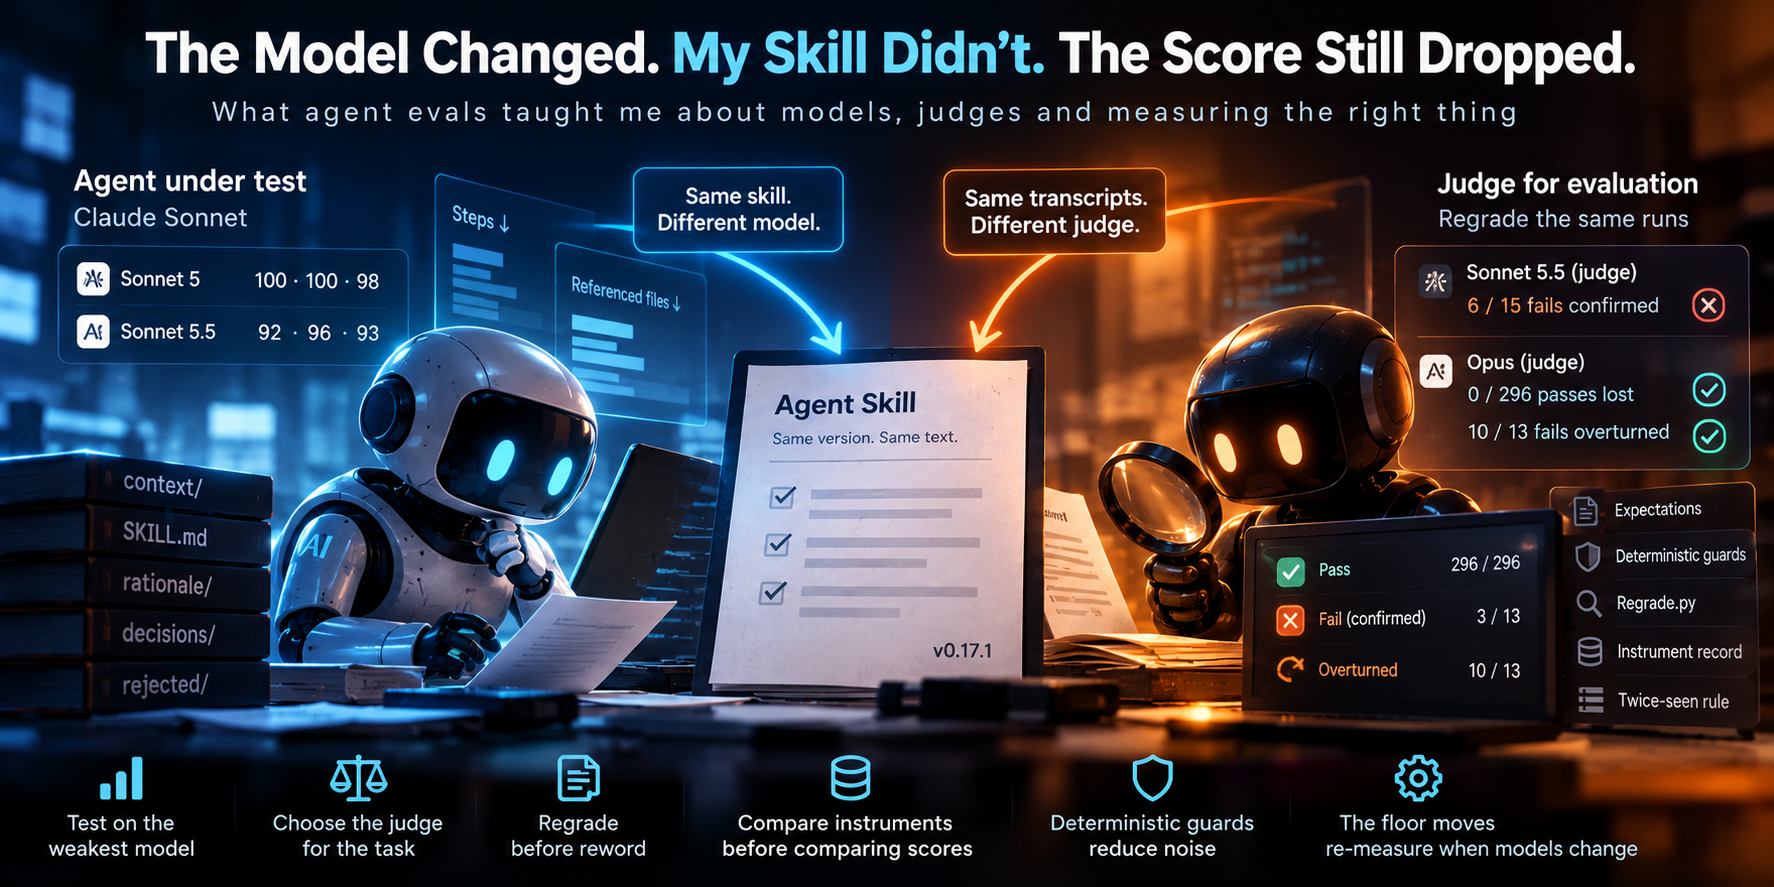
What agent evals taught me about moving model floors, noisy LLM judges, and treating the evaluator as part of the instrument
Rationale, structured knowledge, or codebase intelligence for coding agents?