Session memory is not project memory. It fixes the same complaint.
"My coding agent forgets everything between sessions." Two different things answer that, and they are not competing.
The most common complaint about coding agents is the same on every forum: a new session starts from nothing. The explanation you gave yesterday is gone, the decision you made together is gone, the wrong turn the agent took and you corrected is gone, and tomorrow it proposes it again. Everyone who has worked with an agent for more than a week knows the feeling.
Two different things answer that complaint. They get compared as if they were rivals, and they are layers.
Session memory: what the agent keeps for itself
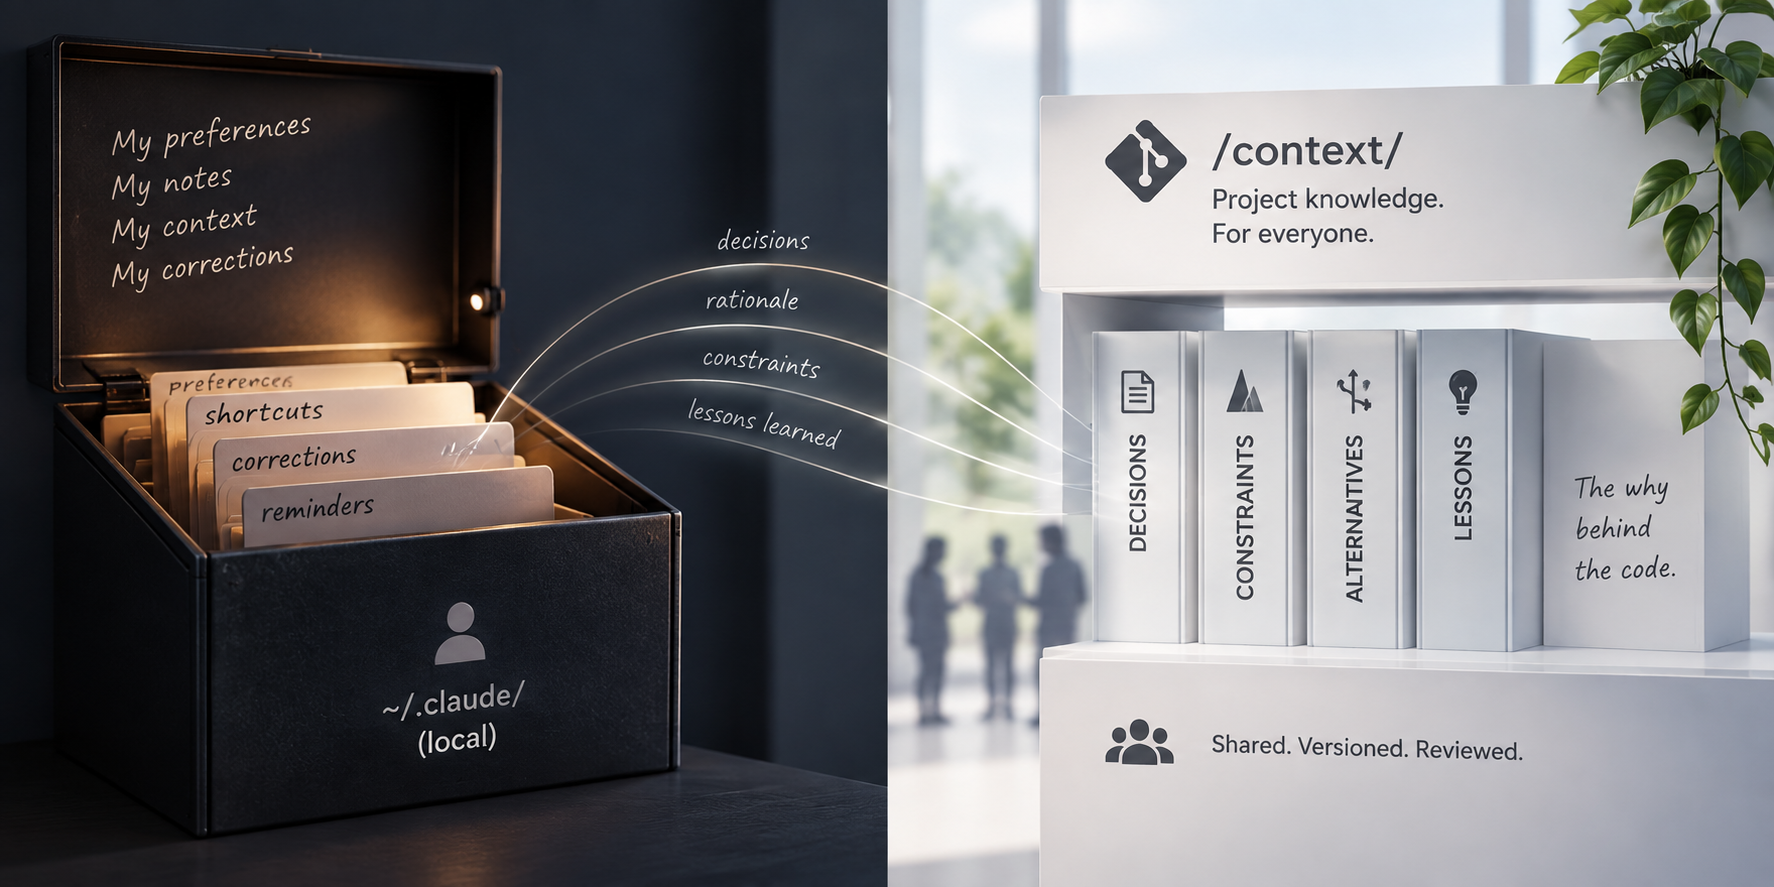
Claude Code's auto memory is the clearest example, because it is built in and on by default. As it works, Claude writes notes for itself: your role and preferences, corrections you gave, project context it can't derive from the code, ongoing work, decisions, and references to things outside the repository. The notes live in a directory on your machine, one per repository, and the first part of the file is loaded into every session. No setup, nothing to decide.
Three properties define it, and none of them is a flaw:
It belongs to one person on one machine. The directory is under your home, not in the repository. A teammate's clone does not have it. Your second laptop does not have it. That is by design: a memory that holds your preferences and your corrections should not automatically travel with the code.
It belongs to one tool. The notes are Claude Code's; Codex, Cursor or Copilot on the same repository do not inherit them.
It is not reviewed with the code. You can inspect and edit the memory, but it is not part of the repository's normal Git and pull-request review flow.
This is the right shape for what it holds. Your preferences are yours. A note like "keep explanations short unless I ask for detail" is between you and your agent. Nobody needs that in a shared project file.
Claude Code also has repository-level CLAUDE.md and AGENTS.md files. Those are shared project instructions rather than auto memory: rules, workflows, architecture and things Claude should do. They can contain rationale too, but rationale is not their dedicated job. The distinction here is specifically between Claude's local auto memory and a repository-native rationale layer.
The complaint session memory answers is: the agent forgot what I told it.
Project memory: what the repository keeps for everyone
A repository already is a project's memory, and has been for decades. The README says what it is, the docs how to use it, the tests what it must do, the changelog what changed, the history who changed it and when. Whoever has the clone has all of it, in every tool, on every machine, reviewed in every pull request.
What the classic layout never had a clear place for is the why: the decision, the alternative that was rejected and the reason it lost, the constraint the code doesn't show, the workaround that must not be cleaned up. That reasoning used to live in people's heads, and left with them.
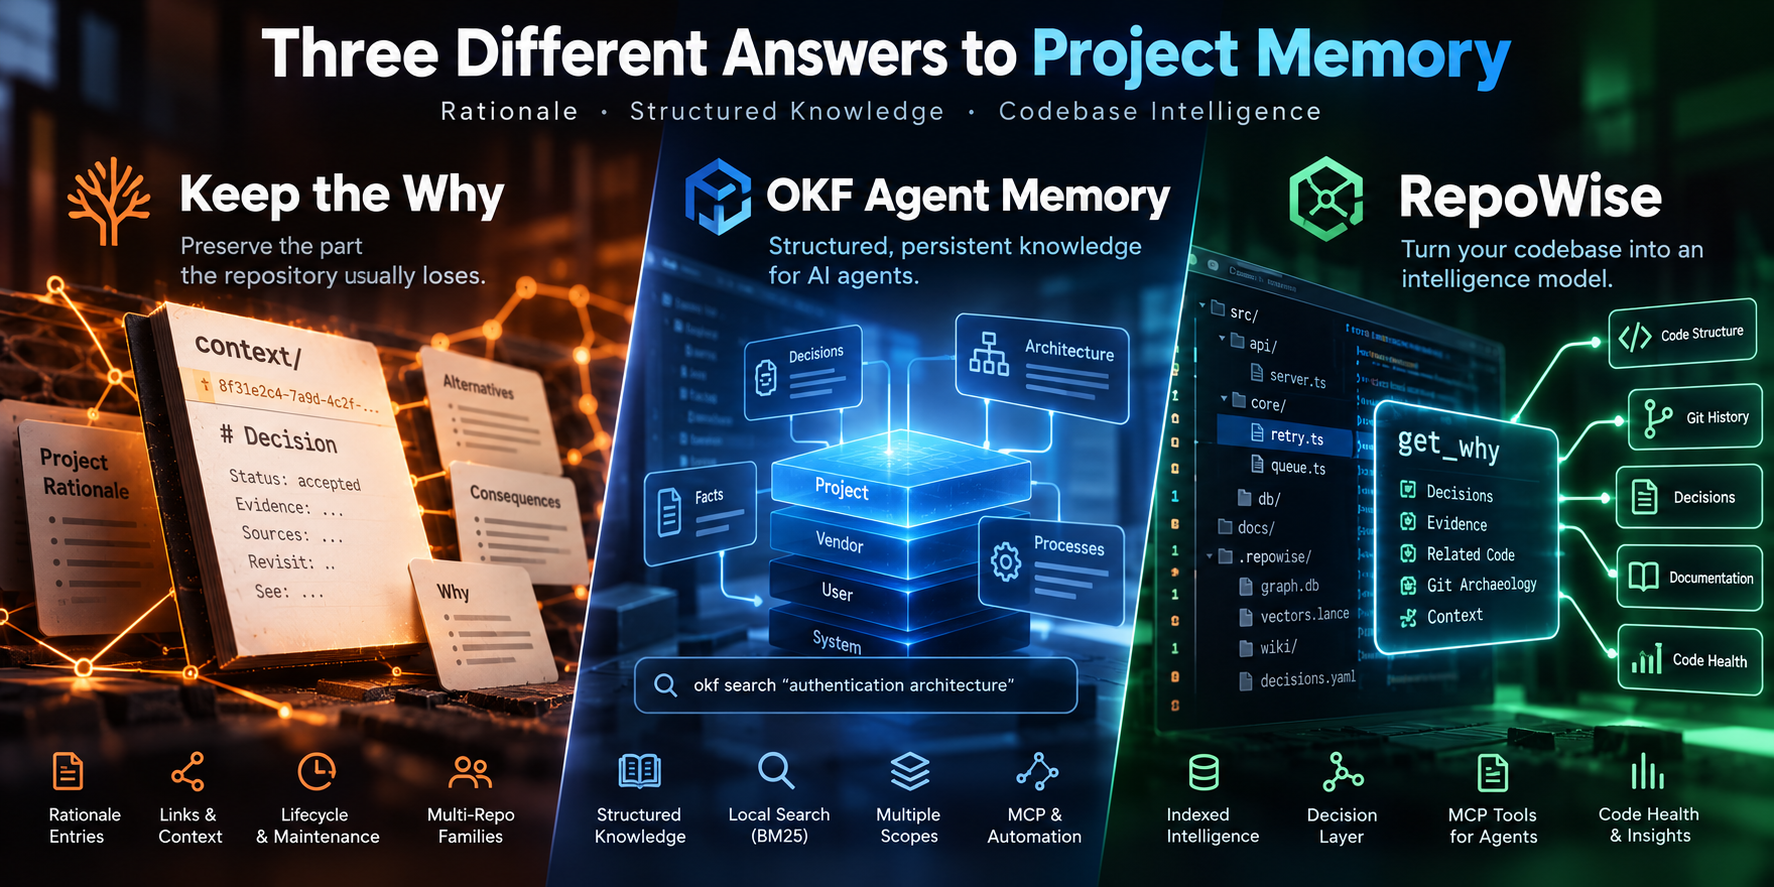
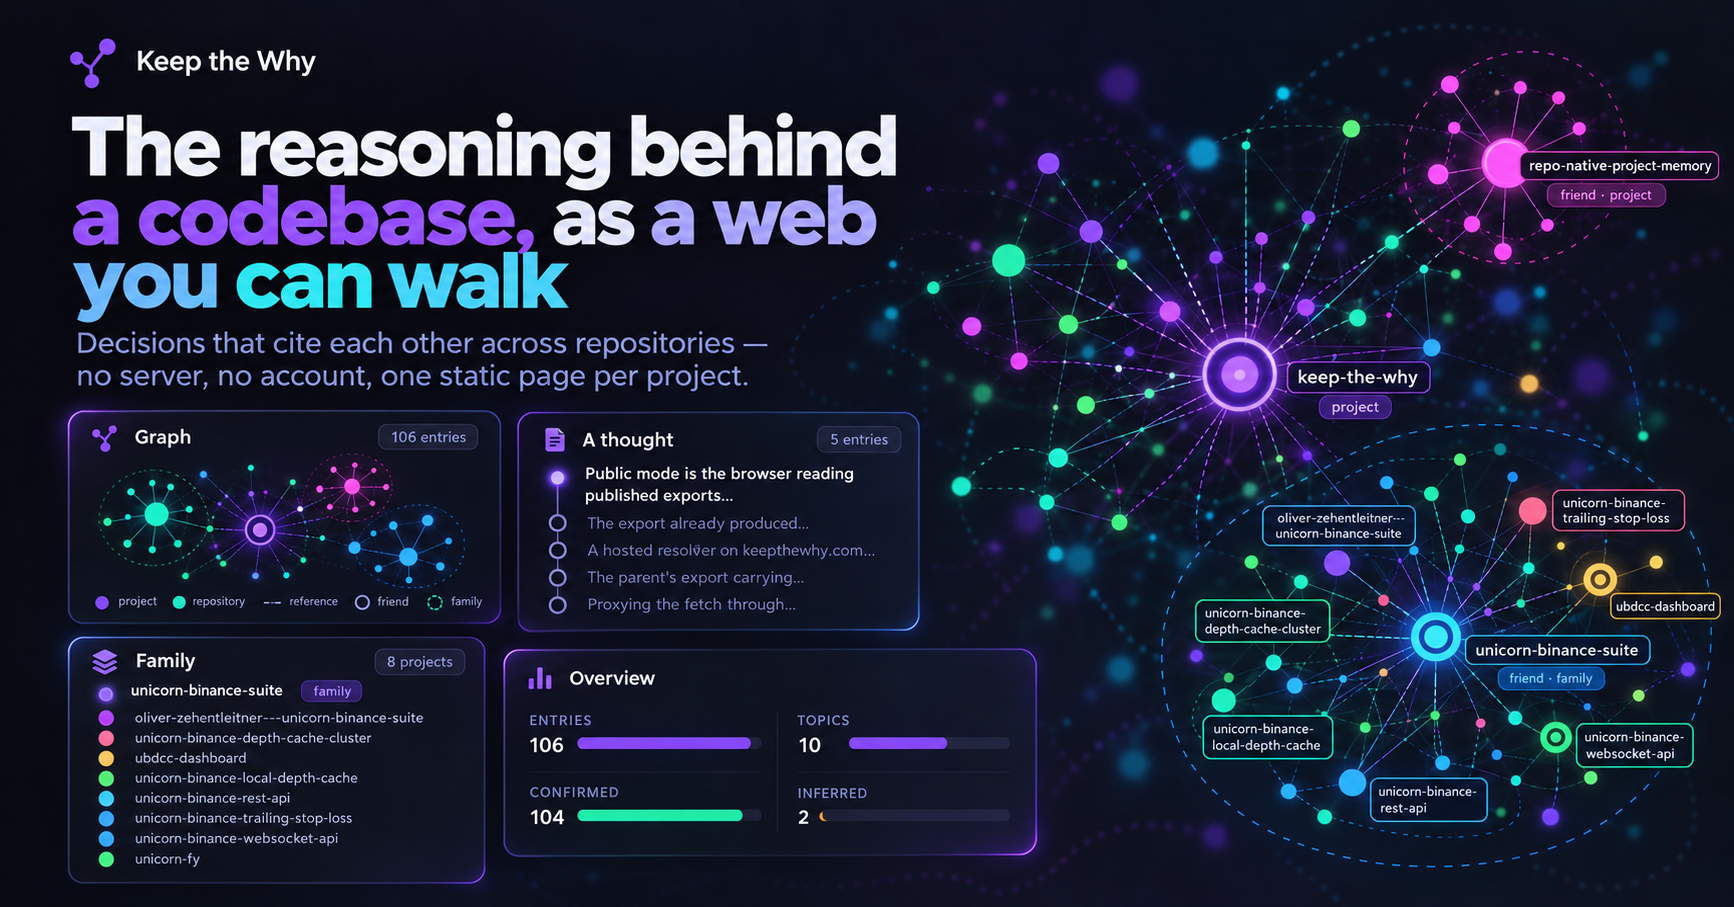
Keep the Why is the convention and the agent skill for that layer: the agent writes the reasoning into context/ as it comes up in the session, as Markdown, committed with the code.
Three properties again, and they are the mirror image:
It belongs to the project. It is in the repository, so the clone carries it. Your teammate's agent can read the same file yours wrote.
It belongs to no tool. Any agent that can read the repository can read it, and switching tools does not remove the information.
It is reviewed. The why arrives in the same pull request as the code, and a wrong entry is a diff somebody can see.
The complaint project memory answers is: the agent forgot why the code is the way it is.
The same complaint, two answers
"The agent forgets" covers several different losses. Sort them and the answer sorts itself:
| What the agent forgot | Which memory answers it |
|---|---|
| that you prefer short commit messages | session memory: personal, one tool, one machine |
| what you two did yesterday afternoon | session memory, or git log |
| where the staging dashboard is | session memory as a personal reference, or the README if the team needs it |
| that the plain retry loop was rejected, and why | project memory, the why layer |
| that the ugly workaround exists because of a rate limiter | project memory, the why layer |
| that a teammate's agent already found the migration trap | project memory: it has to reach the other machine |
The last three are the ones that come back as production incidents when they are lost.
A session memory may remember those facts locally. What it cannot do by itself is make them shared project knowledge across people, machines and tools.
That is the important distinction.
Why you keep both
The temptation is to pick one. Both directions are wrong.
Putting the why only into a personal memory is where many people start, because it is zero setup. It works until the second person, the second machine or the second tool. At that point the reasoning may still exist, but it is trapped in a memory the rest of the project does not carry.
Putting personal preferences into the repository is the opposite mistake. A shared context/ that holds one developer's habits is noise for everyone else, and a privacy problem on top.
Keep the Why refuses that on purpose: personal settings live outside the project, in the developer's own home directory, and the skill does not record who said what.
So: session memory for what is yours, project memory for what belongs to the project.
Leave auto memory on. Give the repository a why layer.
They may remember the same fact. Only one of them makes it part of the project.
The test
Clone the repository on a machine that has never seen it. Open it with a tool you have not used on it before. Hand it to a colleague.
What is still available to the agent is project memory. What has disappeared was session memory, however good that memory was on your laptop.
The complaint "my agent forgets everything between sessions" is really two complaints, and only one of them was ever about the session.
I hope you found this informative and useful.
Follow me on GitHub, Bluesky, Mastodon, X, and LinkedIn, or join Telegram for updates on my latest publications. Constructive feedback is always appreciated.
Thank you for reading, and happy coding! ¯\_(ツ)_/¯