One Index, Many Writers: Avoiding Git Merge Conflicts with Deterministic Write Areas
How a small structural change reduced unnecessary Git conflicts in a shared Markdown index — and made it easier for coding agents to navigate.
While working on Keep the Why, I ran into a very ordinary Git problem.
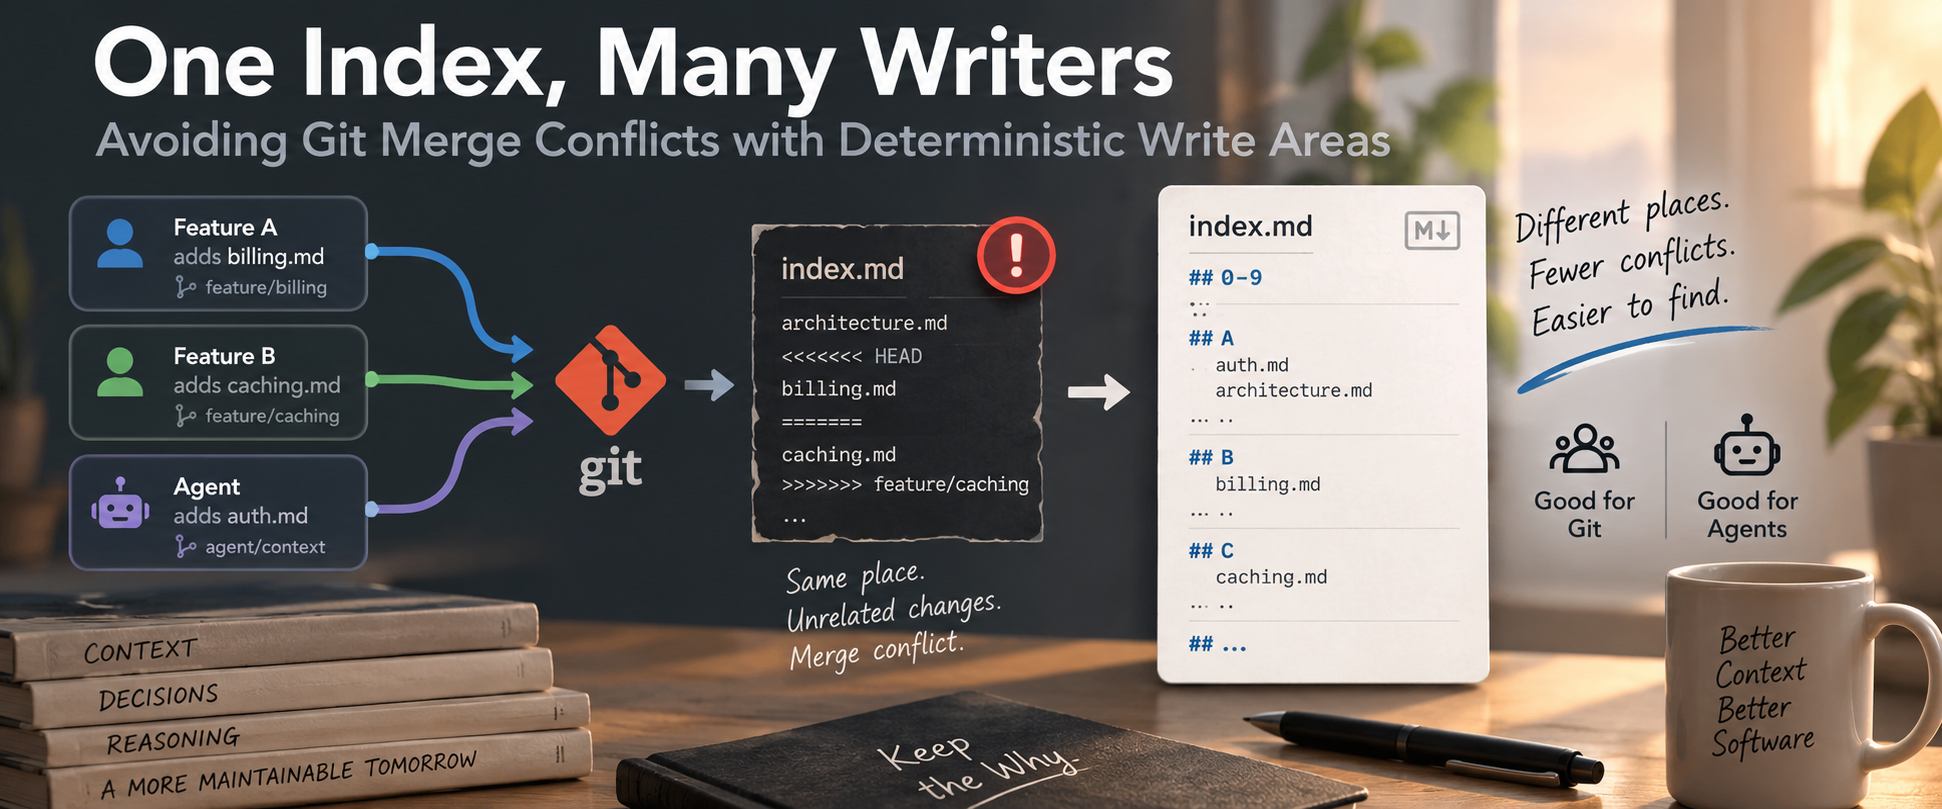
There is one shared context/index.md.
Developers and coding agents can add new context files in different branches. The changes are unrelated, but they are not written back to the repository at the same time. Git has to merge them later.
That is where things get interesting.
Imagine two branches.
One adds:
billing.md
Another adds:
caching.md
Both also update context/index.md.
If new entries are simply appended to the end of the file, both branches modify the same place.
Git sees overlapping changes.
Merge conflict.
The conflict is not semantic. Nobody disagrees about the content. It only exists because several writers use the same file and their changes are integrated later.
This came up in Keep the Why issue #194.
Alphabetical sorting helps, but not enough
My first thought was simple: stop appending new entries and keep the index alphabetically sorted.
That already spreads changes across the file.
But especially with a small index, it does not solve the problem.
Suppose the index contains only:
architecture
deployment
One branch adds:
billing
Another adds:
caching
Both additions belong between the same two existing lines.
So even though the entries are different and correctly sorted, Git can still see both branches changing the same area.
The interesting part is that this problem is actually worse while the index is still small.
With only a few existing entries, there are only a few natural places where Git can anchor an insertion. New entries therefore have a relatively high chance of landing in the same gap.
As the index grows, this usually improves by itself.
More existing entries create more separation points:
architecture
billing
caching
deployment
logging
monitoring
A new entry is now much more likely to land in its own area.
So the main problem is not a large index.
It is a sparse index with several delayed writers.
Creating the structure before it is needed
The solution I implemented is simple.
Every new index starts with fixed sections:
## 0
## 1
## 2
...
## 9

## A
## B
## C
...
## Z
All 36 sections exist from the beginning, even when they are empty.
A topic is inserted below the section matching the first character of its filename.
For example:
billing.md     -> B
caching.md     -> C
deployment.md  -> D
The important part is not really the alphabet.
The important part is that the write areas already exist before concurrent branches need them.
Instead of every new entry competing for one append position, changes are distributed across predefined parts of the file.
The headings become stable merge anchors.
In other words, the index gets some structure early instead of waiting for the content itself to create enough structure later.
A useful side effect for coding agents
The original problem came from Git.
But the fixed structure also makes the index nicer for agents.
An agent does not have to treat index.md as one unstructured Markdown block. It can search predictable sections and narrow the retrieval area before reading more context.
So the same structure gives two benefits:
Git gets stable places for independent changes to land.
Coding agents get predictable places to search.
That was not the original reason for the change, but it fits the way Keep the Why is supposed to work: simple, deterministic retrieval first, deeper reading only when necessary.
What I like about this solution
There is no database.
No locking.
No generated index.
No merge driver.
No additional service.
Just a little bit of structure added before it is actually needed.
The funny part is that once the index becomes larger, the entries themselves increasingly provide the separation Git needs. The fixed 0-9 and A-Z sections are mostly there to make the early and sparse state behave better.
It is a small change, but I like the general lesson behind it:
When many independent writers modify one Git-managed file, avoiding conflicts can be less about smarter merging and more about designing where changes are allowed to land.
I hope you found this informative and useful.
Follow me on GitHub, Bluesky, Mastodon, X, and LinkedIn, or join Telegram for updates on my latest publications. Constructive feedback is always appreciated.
Thank you for reading, and happy coding! ¯\_(ツ)_/¯